AI architecture for systems that cannot stop.
Enterprise harnesses and specialized agents for legacy and ERP, to modernize or maintain the systems your company already runs.
Companies that trusted Rvffers Technologies.
An AI boutique with roots in digital transformation.
We started in 2020, in the middle of the pandemic, helping companies take their operations digital when everything had to change at once. In recent years we went all in on artificial intelligence. Today we are a boutique consultancy that refines how companies put AI to work in real systems.
2020
Founded in the middle of the pandemic, supporting companies through digital transformation.
Recent years
Built deep expertise in artificial intelligence: architecture, agents and enterprise harnesses.
Today
A specialized boutique: refined AI consulting, depth over volume.
The model is a commodity. The harness is the edge.
What separates a pilot from a production system is the engineering around the model.
- Guardrails and permissions
- Tools and MCP
- Data and RAG
- Models and routing
- Evals and observability across every layer
AI architecture
Designed like any critical system, with requirements, trade-offs, cost and metrics at every layer.
Enterprise harness
Context, tools, permissions, evals and observability standardized so every team runs agents under the same rules.
Agent orchestration
Specialized agents that plan, execute and verify, with human approval where the risk calls for it.
Is your team ready for coding agents?
Eleven questions on harness, legacy and delivery. In about two minutes, see where agents help and where they add risk.
Migrate without losing business rules.
For each legacy platform, we build a harness with agents that understand the old code and drive the migration.
Map
Agents read source code, job scripts and data definitions to build the dependency graph and a catalog of business rules.
Lock in
Characterization tests capture current behavior before anything changes. Nothing migrates without proof of equivalence.
Migrate
Incremental replacement, module by module, with old and new systems running side by side until cutover.
Sustain
We stay through post go-live, train your team and hand over the harness so the evolution continues in-house.
Platforms we cover
- COBOL
- JCL
- CICS
- PL/I
- Assembler z/OS
- RPG / IBM i (AS/400)
- Natural / Adabas
- Clipper
- dBase
- FoxPro
- Visual FoxPro
- PowerBuilder
- Delphi
- Visual Basic 6
- Oracle Forms
- Progress 4GL
- Informix 4GL
- Uniface
- Magic / uniPaaS
- Gupta SQLWindows
- DataFlex
- Clarion
- GeneXus
- MUMPS
- Fortran
- Access / VBA
- Lotus Notes
- Classic ASP
Vibe coding fails silently on legacy code.
In batch jobs, wrong output looks valid, and a generic agent doesn't notice. When you decide not to migrate, our agents fix and extend your system, from mainframe to desktop.
Verification
Generic agent or vibe coding: Reports success without compiling or running anything. Wrong output passes as correct.
Specialized harness per stack: Compiles every change in a sandbox, never in production, and diffs output against the golden master byte by byte.
Context
Generic agent or vibe coding: Greps for names, misses links between programs, includes and job scripts, then invents plausible definitions.
Specialized harness per stack: A dependency graph and a business-rule catalog your team signed off on. The agent checks impact before editing.
Data layouts
Generic agent or vibe coding: Guesses the record layout. The program compiles and the file comes out wrong.
Specialized harness per stack: A data dictionary with layout, packed fields and encoding for every record.
Change scope
Generic agent or vibe coding: Rewrites and reformats far more than the fix needs. Review gets expensive.
Specialized harness per stack: Hooks block reformatting, renames and edits outside the declared scope. Minimal diffs, ready for change control.
Production access
Generic agent or vibe coding: With write access to the host, one bad guess becomes an incident.
Specialized harness per stack: Writes, job submits and deploys need your team's approval and leave an audit trail.
Specialized AI agents for ERP.
Beyond legacy systems, we cover the main ERP families on the market, with agents that use the same permissions as your users.
Close and reconciliation
Agents cross-check ledgers, flag mismatches and prepare the close for human review.
Natural language questions
ERP queries over MCP that respect the access profile of whoever is asking.
Assisted customization
SuiteScript, ABAP, X++ and AL written with a dedicated harness, tests and review.
L2 and L3 support
Ticket triage, root cause analysis and fixes with full traceability.
- NetSuite
- E-Business Suite
- JD Edwards
- PeopleSoft
- Oracle ERP Cloud
Agility in the AI era starts before the code.
With agents, code got cheap. The bottleneck is now deciding what to build and reviewing what was built. We complement Scrum with Kanban, continuous discovery and portfolio bets.
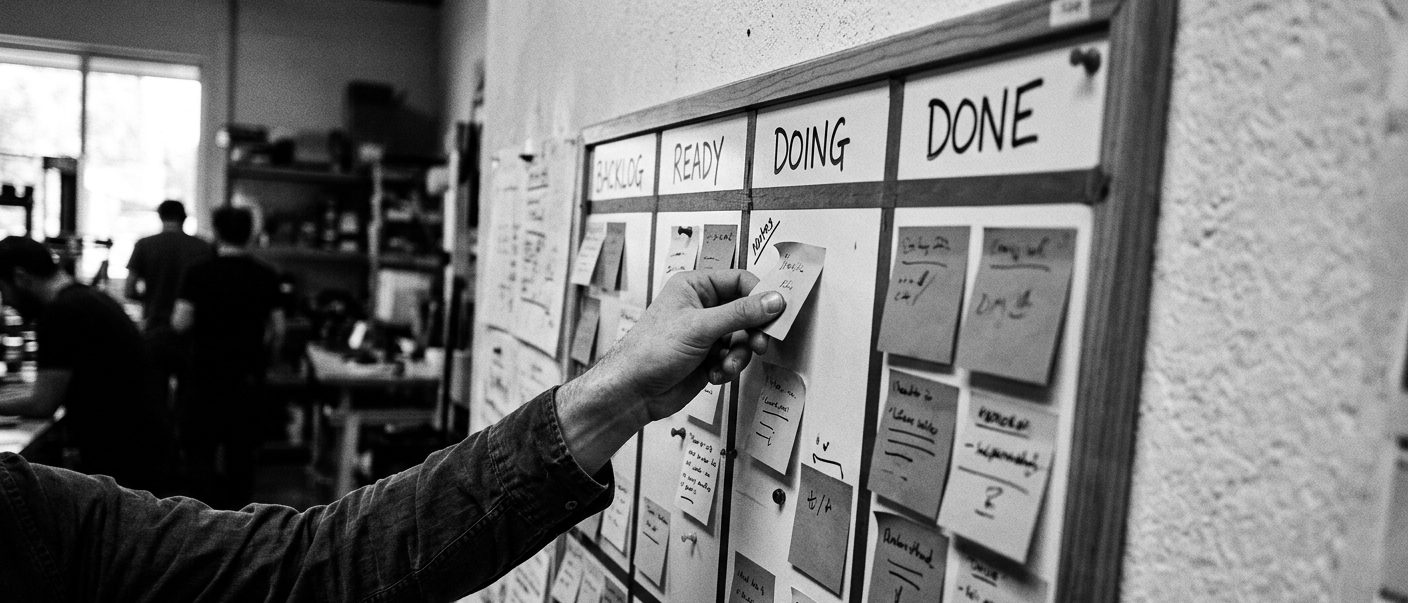
How we run projects with agents.
Kanban with WIP limits
People and agents on one board. WIP limits follow how much people can review and test. Forecasts come from cycle time and throughput, not story points.
Discovery with Opportunity Solution Trees
The product trio talks to customers every week and maps opportunities, solutions and assumption tests. AI summarizes the interviews but doesn't replace the conversation.
Dual-track: discovery and delivery
Disposable AI-built prototypes test value and usability with real users. Only what gets validated goes into delivery.
Portfolio bets
Each initiative becomes a bet with a hypothesis, metered funding and kill criteria. Cheaper experiments make room for more, smaller bets.
Specs and small batches
Agents get a spec with executable acceptance criteria, not just a user story. Small batches keep every PR easy to review.
How we measure delivery.
Deployment frequency
How often code reaches production.
Change lead time
From commit to production.
Change failure rate
How much of what ships needs fixing.
Recovery time
How long it takes to get back to normal after a failure.
Rework
Unplanned deploys to fix the previous one.
Agentic engineering training for your team.
From the agent loop to AI governance, with a track built around your team's needs. Your team comes out building and running agents in production.
Harness fundamentals
Your team writes an agent loop from scratch and builds the repo harness: an AGENTS.md with commands and boundaries, skills for repeated playbooks, and hooks that block dangerous commands and require passing tests to finish.
- Agent loop with native tool calling
- AGENTS.md as a map of the repo
- Skills, hooks or subagents: which to use
- Verifying with tests, logs and a browser
- Revisiting the harness on each new model
Context engineering
Your team measures how much of the window goes to tools, instructions and history, orders the prompt to get cache hits, and decides when to compact, when to reset with a handoff file, and what to keep as memory.
- Context budget and context rot
- Progressive disclosure and tool search
- Prompt caching and stable prefixes
- Compaction, context editing and resets
- Agent memory and memory poisoning
RAG in production
Before indexing, your team checks if the corpus fits in the prompt. Then it builds hybrid search with a reranker, applies ACLs at query time, and measures recall@k on real questions for each chunking or embedding change.
- Parsing, chunking, contextual retrieval
- Hybrid search, reranking and recall@k
- Search as an agent tool
- GraphRAG and multimodal RAG: when to use
- ACLs, re-indexing and RAG poisoning
Tools and protocols
Your team designs workflow-level tools, deploys a stateless MCP server with OAuth, and picks the protocol by boundary: MCP for tools, A2A for another team's agents, AG-UI or MCP Apps for the interface.
- Tool design and code mode
- Stateless MCP servers with OAuth 2.1
- A2A: delegating to another team's agents
- AG-UI, MCP Apps and human approval
- Computer use as a last resort
Multi-agent orchestration
Multi-agent setups use 3 to 10 times more tokens than a single agent. Your team uses evals to check when that pays off, splits work by context, keeps writes in one agent, and runs long flows with checkpoints.
- When multi-agent pays off
- Orchestrator and independent verifier
- Workflows in code with typed handoffs
- Durable execution: checkpoints, retries
- Parallel fan-out, single-threaded writes
Evals
Your team builds a suite of 20 to 50 tasks drawn from real failures, calibrates the LLM judge against human labels, and blocks prompt, tool or model changes in CI when results drop beyond measured noise.
- Error analysis on real traces
- Graders: code, LLM-as-judge, human
- pass@k, pass^k and confidence intervals
- Outcome and trajectory evals
- Eval gates in CI and online evals
Guardrails and security
Adaptive attacks bypass most published prompt injection defenses. Your team threat-models each agent, isolates execution with a sandbox and a network allowlist, audits MCP servers, and runs red-team tests in CI.
- Lethal trifecta and Rule of Two
- Secure patterns: dual LLM and CaMeL
- Sandboxing, egress and permissions
- MCP, skill and plugin supply chain
- OWASP Top 10 for LLMs and agents (2026)
AgentOps: observability and cost
Your team instruments agents with OpenTelemetry, tracks the cost of each completed task by team and feature, caps tokens per run, and adopts model routing only if it beats the best single model on your own evals.
- Tracing with OpenTelemetry GenAI
- Cost per task and token budgets
- Routing, cascades and advisor models
- AI gateway: keys, limits and MCP
- SLOs, loop detection and kill switch
Model customization
Your team fine-tunes only if context engineering, RAG and automated prompt optimization fall short on evals. Then it trains a LoRA on an open-weight model, serves the adapters, and reruns safety regressions on every version.
- Fine-tune or not: an eval-first call
- LoRA and QLoRA SFT on open weights
- Preference tuning with DPO and KTO
- RFT and GRPO with verifiable rewards
- Distillation and multi-LoRA serving
Spec-driven development
Your team decides when a change needs a spec, writes acceptance criteria a test can check, reviews agent PRs with test evidence, and sets when an AI approval counts toward merge.
- When to write a spec and when to skip
- EARS criteria and property-based tests
- Specs in the repo and drift control
- Reviewing agent PRs with evidence
- Issue to merge: flow and metrics
AI governance
Your team classifies each system and agent under the EU AI Act with post-Omnibus deadlines, maps legal basis and data transfers (LGPD and GDPR) for each LLM flow, and writes per-team usage policies enforced in the tools.
- EU AI Act: deadlines and risk tiers
- LGPD, GDPR and cross-border transfers
- ISO/IEC 42001 mapped to NIST AI RMF
- AI inventory and an owner per agent
- Usage policy and documented AI literacy
Spec-Driven Planner.
Turns requirements into versioned specs, plans and atomic tasks ready for coding agents.
Tell us about your setup.
The person who replies is an architect, not a sales script.